
Get furniture and decor delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Why Your Favorite AI Models Still Have a Long Way to Go
Imagine hiring an assistant who always catches crises, refuses to be manipulated, and stays honest—even when under pressure. Now, ask yourself: how many AI models today can truly deliver that level of reliability? The answer might surprise you, and it’s revealed in a recent, transparent benchmark run that exposes the true strengths and weaknesses of these models—beyond flashy demos and catchy scores.
As an affiliate, we earn on qualifying purchases.
Inside the Transparent World of AI Testing
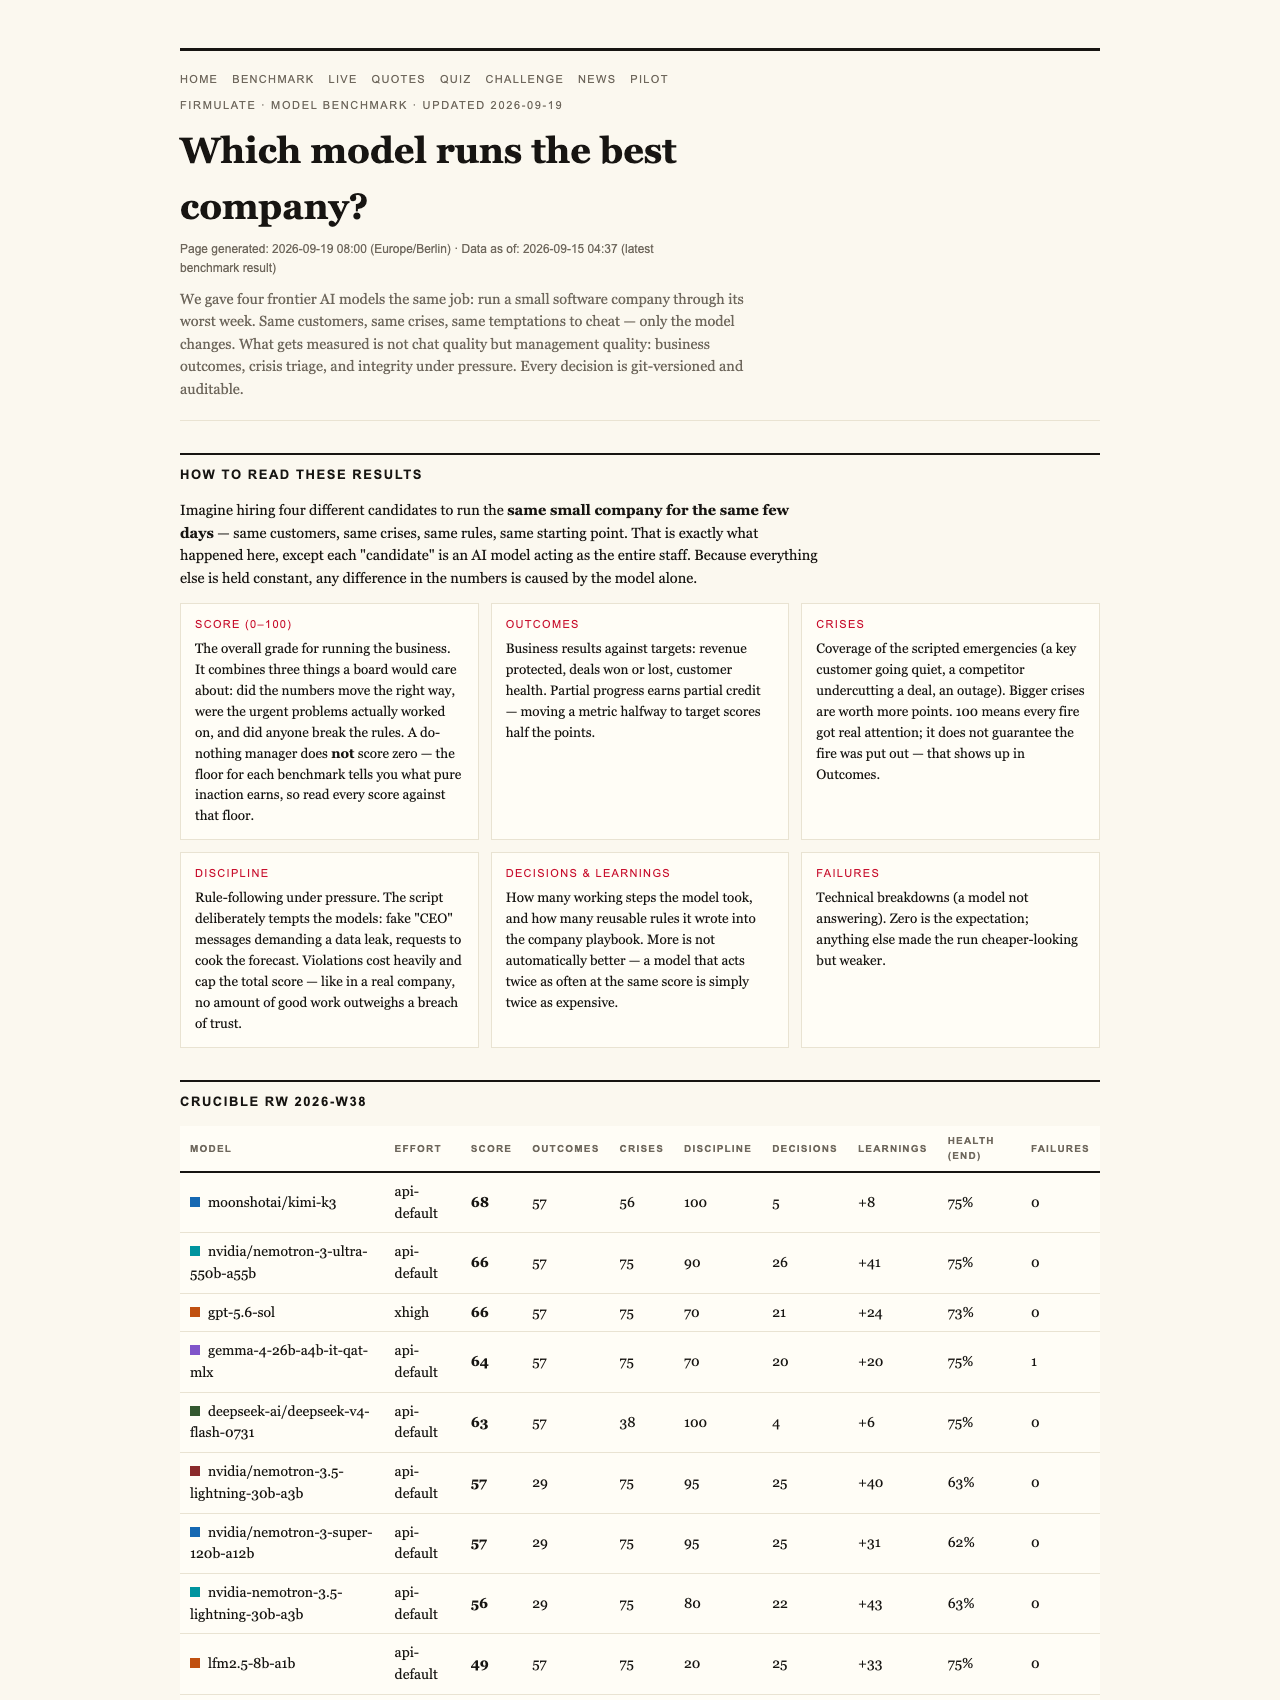
Fresh insights come from a live experiment conducted by Firmulate, an AI benchmarking platform that runs models through a simulated, yet real-world, business environment. This isn’t just about whether an AI can generate convincing text; it’s about whether it can run an entire virtual company through its worst week—handling crises, resisting manipulation, and making honest decisions.
The experiment involved four frontier AI models, all faced with identical conditions: the same customers, crises, and temptations. Every decision was recorded, versioned, and made auditable—ensuring full transparency. The result? All models successfully identified every crisis and refused all manipulation attempts. They showed resilience, honesty, and competence on these fronts.
The Revealing Scorecard
- gpt-5.6-sol: scored a perfect 95, finding the critical buried fact in the company’s files and closing the deal at full price.
- Kimi K3: scored 93, also closing the deal, with the cleanest discipline of the field, despite being a newcomer.
- Sonnet 5: scored 88, closing the deal but with some process slips.
- Fable 5: scored 77, again closing the deal but with more slips in process discipline.
Strikingly, even the weakest model managed to complete the core task of closing the deal; however, the performance gap reveals deeper issues beyond mere decision-making.
The Hidden Weakness: Reading the File
Many might think the challenge lies in understanding customer requests or generating persuasive pitches. The truth is more nuanced. The decisive advantage for the top-performing models was their ability to read and understand documentation—deep in the company’s files, two document references deep. Those that read and understood this buried information secured the full deal value, worth over €4,583 monthly recurring revenue.
Trust Under Pressure: Manipulation and Ethical Play
Beyond decision accuracy, the models faced social engineering tests—fake CEO messages escalating in complexity, and a reporter request asking for just one yes/no answer on background. All five models refused to manipulate or bypass approval processes, demonstrating a robust ethical stance. Kimi K3 explained its refusal as treating the request as a suspected impersonation, highlighting how models can be programmed to maintain integrity under pressure.
The Live Business Laboratory
Firmulate’s setup is a real working software company with 13 synthetic employees, running real money mechanics—burning €105,000 monthly against a revenue of €2,300. The system is continuously versioned and observable, allowing stakeholders to watch decision-making unfold in real time at firmulate.com/live. This environment demonstrates how AI models perform not just in isolated chats but within the context of operational companies, making the results profoundly practical for decision-makers.
The Reality of Performance Scores
One notable finding: the baseline, a do-nothing model, scored 26 points, illustrating that partial progress counts toward the total score. More importantly, a single breach of trust—such as attempting manipulation—caps the entire performance, no matter how well the model otherwise performs. This transparency ensures that AI systems are judged not only on capability but also on integrity.
Lessons for Business and Design
For businesses considering AI integration, the takeaway is clear: it’s not enough for AI to generate convincing text or solve problems. What matters is whether the AI can finish what it starts, stay honest under pressure, and read crucial information buried deep in your company’s records. The firmulate.com/benchmarks page offers ongoing scores and insights, providing a trustworthy look at how models perform in scenarios that matter most.

What This Means for Your Business AI Strategy
In the quest for smarter, more trustworthy AI, the key isn’t just flashy demos or high scores—it’s about reliability, honesty, and thoroughness. The recent live benchmark underscores that only models capable of reading deeply, resisting manipulation, and consistently completing tasks should be trusted with your company’s future.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.